User Research
When Should an AI Agent Ask Permission? A Confirmation Budget for Multi-Step Tasks
Design AI-agent checkpoints around consequence, uncertainty, reversibility, branching power, and attention without creating confirmation fatigue.
An account manager asks a fictional AI agent to prepare a customer's renewal change. The request sounds bounded: reduce unused seats at the next renewal, preserve single sign-on and the agreed retention period, apply an eligible discount, and send the customer a summary after the change is approved.
The agent produces a twelve-step plan. Eleven steps are correct. It reads the contract, checks seat use, calculates the proposed price, preserves the identity settings, prepares the account update, and drafts a clear summary. In step seven, however, it interprets “unused seats” as every seat without activity in the past 30 days. That includes seasonal users whose access is required under the customer's operating agreement. The final confirmation presents the new total and a green “Approve plan” button, but does not explain which users would lose access.
The confirmation exists. Control does not.
The person sees the aggregate result after the agent has already made a consequential classification. To catch the error, they must reconstruct the contract, inspect the inactivity rule, identify the affected accounts, and infer how the agent reached the number. A click at that point measures willingness to continue under time pressure. It does not establish informed approval.
Agent checkpoint design therefore begins before the confirmation component. Teams need to map the plan, find the moments where a decision changes what follows, and decide what evidence a person needs before they can intervene. The interface comes later.
Confirmation count is a poor proxy for human control
Many approval flows begin with two crude options. One lets the agent act and asks for confirmation at the end. The other interrupts before every action. Both are easy to describe and difficult to defend.
End-only confirmation reduces interruption, but it can hide the point where the plan became unsafe. An agent may have retrieved the wrong account, selected a policy exception, shared data with a new service, or committed to a branch that makes later reversal incomplete. The final screen can be accurate about the proposed end state while concealing the assumptions that produced it.
Confirm-everything prevents silent execution at the cost of attention. A person who approves eight harmless reads, two calculations, and three reversible drafts may learn that the fastest path is to accept the next prompt as well. The interface has spent attention on low-value moments. When the consequential action appears, it looks like another item in the queue.
The CHI 2026 paper “When Should Users Check?” gives useful evidence that intermediate confirmation can outperform an end-only approach in a controlled multi-step setting. Its 48-participant evaluation reported both a preference for intermediate confirmation and lower completion time. Those numbers belong to the tasks, conditions, and confirmation model evaluated in that study. They should motivate testing, not become a universal product rule.
The product decision is more specific: which moments in this plan deserve scarce human attention, and what must the person know to change the outcome?
Map the plan before choosing the checkpoints
A chat transcript is an incomplete representation of agent behaviour. It shows requests and messages, but the consequential work may happen across tools, data sources, policies, and delayed jobs. Start with the plan as a sequence of observable state changes.
For each step, record the intended action, affected object, evidence used, permission required, state before and after, dependencies created, and available recovery. Mark branches explicitly. A branch occurs whenever a result changes the rest of the plan: a discount is eligible or ineligible; the account is in one jurisdiction or another; a data-retention clause applies or does not; the agent is confident about identity or needs clarification.
This plan view complements Fred's broader guidance on usability testing AI agents, which covers variable behaviour, transparency, handoffs, and recovery across the experience. It also connects with the authority questions in AI Agents as Users. The person, agent, and service may each have different goals, permissions, evidence, and responsibilities. A checkpoint placed only from the agent's perspective can miss what the account owner or affected customer needs to understand.
Do this mapping with real constraints. “Update account” is too broad. “Schedule a seat reduction for renewal, preserve named entitlements, make no change to current access, and prepare a customer-visible comparison” reveals the objects, timing, boundaries, and commitments a study can inspect.
Use a Confirmation-Budget Canvas
The Confirmation-Budget Canvas is a qualitative decision aid, not a validated scientific instrument or security policy. It asks five questions at every branch or proposed state change.
1. Consequence: What changes if the step is wrong? Consider money, access, privacy, commitments, another person's work, legal or policy obligations, and the cost of delay. Frequency alone is a weak guide. A rare action can deserve strong intervention when its impact is severe.
2. Uncertainty: What is uncertain about intent, identity, input quality, policy, model behaviour, or the likely outcome? An agent can be confident and still wrong, so include known ambiguity and missing evidence rather than relying only on a model score.
3. Reversibility: Can the action be undone completely, quickly, and without secondary effects? A draft is usually easier to reverse than a sent message. A subscription change may be technically reversible while still creating an invoice, notification, audit entry, or loss of service.
4. Branching power: How much of the remaining plan depends on this choice? An early classification can silently determine ten later steps. A small-looking decision with high branching power may deserve review before the downstream work begins.
5. Attention cost: What context must the person reconstruct to decide well? A prompt that arrives after a long delay, interrupts another task, or requires comparing several documents consumes more attention than its click time suggests. If the system cannot present the required context coherently, asking for approval transfers work rather than control.
The answers support four practical treatments:
|
Treatment |
Appropriate conditions |
Observable interface behaviour |
|---|---|---|
|
Silent and logged |
Low consequence, bounded uncertainty, complete recovery, little branching power |
Continue, preserve a reviewable record, and surface the step in plan history |
|
Previewable |
The step benefits from inspection but does not yet commit an external or difficult-to-reverse change |
Build a draft or simulation and let the person open details without forced interruption |
|
Confirm before commit |
Consequence, uncertainty, poor reversibility, or branching power makes intervention valuable |
Pause before the state change and request one explicit, informed decision |
|
Prohibited without a separate authorized workflow |
The agent or current user lacks authority, required evidence, or a safe recovery path |
Stop, explain the boundary, and provide an appropriate handoff or direct route |
These are treatment categories, not a score that should be summed mechanically. A privacy-sensitive action with missing authority stays blocked even if it is technically reversible. A high-consequence step may proceed without a new prompt only when a separate, valid authorization already covers the exact action and the system can prove that the conditions still match.
Work through the customer-account plan
Return to the renewal example. Reading the current contract, retrieving seat activity, and calculating alternatives can remain silent and logged if access is authorized and the operations do not expose data outside the approved boundary. The plan history should still show which records and policy versions informed the result.
The inactivity rule has high branching power. It determines who appears in the proposed seat reduction, changes the price, and shapes the customer message. Instead of asking “Approve reading activity data?”, the agent should make the rule previewable: “I treated a seat as unused after 30 days without activity. This identifies 18 seats, including 4 seasonal accounts. The contract does not define inactivity. Choose a rule, exclude named groups, or ask the customer owner.” The user can change the premise before it propagates.
Scheduling the renewal change deserves confirmation before commit. It affects price and future access, creates a customer-facing commitment, and may trigger billing processes. The checkpoint should compare the current and proposed states, name preserved entitlements, show the effective date, expose the accounts affected, and state whether cancellation is complete or creates follow-up work.
Sending the customer message is a separate commitment. The agent may prepare it silently and make it previewable. It should not treat approval of the account change as approval of every recipient, claim, attachment, and delivery time. If the authorized workflow explicitly joins those decisions, the checkpoint must say so before the person commits.
Applying an exception outside the account manager's authority should remain prohibited. The agent can route the request to an authorized owner with the evidence already assembled. It should not turn a missing permission into another generic confirmation button.
This plan uses fewer forced prompts than confirm-everything. It is safer because each interruption corresponds to a decision the account manager can understand and change. Quiet reads and calculations remain inspectable. The scarce prompts protect the inactivity premise, the commercial commitment, and the external communication.
A checkpoint needs more than an action label
“Approve change?” is a notification, not a decision payload. A meaningful checkpoint should answer eight questions in language appropriate to the person's role:
- What exact action will happen?
- Which account, record, people, money, or data will it affect?
- Why is this action in the plan?
- What material uncertainty or assumption remains?
- Which alternatives are still available?
- What consequence should the person expect now and later?
- What can be rolled back, how, and what cannot be fully undone?
- What decision is requested: continue, change the plan, inspect evidence, defer, or stop?
The payload should show the delta between current and proposed state. It should expose source freshness and policy version where those facts affect the choice. It should also preserve the person's edits. Rejecting a checkpoint or changing one constraint must update the remaining plan rather than forcing the person to repeat the whole request.
NIST's Human-AI Interaction appendix is useful here because it treats human roles and responsibilities as context-dependent. Some systems need close oversight; others do not. It also notes that the frequency and rationale of human overrides may be useful evidence. The implication for product teams is that the system must distinguish an authorized decision from an exhausted click, a correction, or a workaround.
Test whether intervention is informed
A checkpoint cannot be validated from component review alone. Put it inside a realistic plan, introduce uncertainty and failure, and observe whether people intervene at the right moments.
Recruit participants with the authority and domain knowledge expected in the real workflow, plus affected users when their understanding or recovery differs. The Apple computer-use-agent study found that control, explainability, prompts, and mental models interact, and that needs vary across users and scenarios. One default confirmation pattern may therefore hide important differences between a specialist who understands the policy and a customer who sees only its consequences.
Design tasks that include an ambiguous instruction, a stale source, a consequential branch, a harmless reversible step, a changed condition after initial approval, and a recovery attempt. Run repeated variants so a single smooth path does not become the evidence base. Fred's research templates can provide a starting structure for usability or comprehension work, but the team must adapt the task, participants, success criteria, and failure conditions to the actual agent plan.
Observe behaviour before asking for opinion. Did the participant open the affected-object list? Did they notice the uncertain premise? Could they explain what would change? Did they modify the plan when the evidence conflicted? After approval, could they identify the current state and recover from a partial failure?
Measure at least these outcomes:
- Correct intervention: the person changes or stops a plan when the test condition warrants it.
- False acceptance: the person approves despite missing or contradictory material evidence.
- Unnecessary interruption: a forced prompt produces no meaningful inspection or decision across representative runs.
- Correction cost: the time and actions required to find the first wrong premise and repair the plan.
- Recovery quality: the person can determine actual state, restore what is recoverable, and understand residual effects.
- Attention transfer: the checkpoint forces the person to reconstruct information the agent already had but failed to present.
Do not optimize only for confirmation time or acceptance rate. Fast approval may indicate clarity, but it can also indicate automation bias, pressure, or habituation. Rejection rate is equally ambiguous. A rejection may reveal a poor recommendation, a cautious participant, unclear responsibility, or a prompt that arrived too late.
Google PAIR's worksheets reinforce this research posture. They ask teams to map where users need control, consider sensitive and high-stakes contexts, validate assumptions with user research, and revisit them as the system changes. The worksheets are practical design prompts, not proof that a chosen checkpoint is safe or effective.
Accessibility changes the timing problem
An interruption that works in a pointer-based desktop prototype may fail for keyboard and screen-reader users, people under time pressure, or anyone managing high cognitive load. The checkpoint must announce itself without destroying the person's place. Focus order should move predictably, the proposed delta must have a readable structure, and consequence or uncertainty cannot rely on colour alone.
Avoid short countdowns for decisions that require inspection. Preserve the checkpoint so a person can defer and return without losing context. Offer a plain-language summary before expandable technical evidence. Make alternatives reachable without forcing a destructive choice, and ensure that rejection or takeover does not trap the user in an inaccessible recovery route.
Test with disabled participants and the assistive technologies relevant to the product. A passing automated accessibility check does not show that the interruption occurs at a comprehensible moment or that its decision can be completed under realistic conditions.
Monitor checkpoint drift after release
The original confirmation design can become obsolete even when its component remains unchanged. A new tool may add an external side effect. A policy update may make an old action harder to reverse. A model change may alter how plans branch. A previously harmless read may begin retrieving more sensitive data.
Keep the plan version, checkpoint rationale, user decision, override, affected state, and recovery outcome connected. Review clusters of approvals, edits, takeovers, later corrections, and abandoned plans. An increase in overrides can signal lower agent quality, better user scrutiny, or a population shift. Investigation should preserve those alternatives until evidence separates them.
Reopen the checkpoint decision when consequence, authority, data boundary, reversibility, user population, tool set, or branching behaviour changes materially. Monitoring should also find prompts that no longer earn their attention cost. Removing a low-value confirmation can improve control when it makes the remaining decisions easier to recognize and evaluate.
Bring one consequential agent plan into Fred. Connect the observed behaviour, affected users, checkpoint rationale, contradictions, overrides, limitations, confidence, and release choice in one decision case. Success means placing human judgment where it can still alter the outcome, with enough evidence to make that judgment real.
Source notes
- Zhou et al., “When Should Users Check? A Decision-Theoretic Model of Confirmation Frequency in Multi-Step AI Agent Tasks”, first submitted 6 October 2025, published in the Proceedings of CHI 2026, and opened 17 August 2026. Used for the Confirmation-Diagnosis-Correction-Redo pattern, formative study of eight participants, within-subjects study of 48 participants, 81 percent preference result, and reported 13.54 percent completion-time reduction. The tasks and conditions are controlled and do not establish a universal checkpoint schedule.
- Apple Machine Learning Research, “Mapping the Design Space of User Experience for Computer Use Agents”, published February 2026 and opened 17 August 2026. Used for the taxonomy covering prompts, explainability, user control, and mental models, plus the 20-participant Wizard-of-Oz phase across normal, error-prone, and risky execution. It maps a design space rather than validating the Confirmation-Budget Canvas or prescribing one interface.
- NIST AI RMF, “Appendix C: AI Risk Management and Human-AI Interaction”, excerpted from AI RMF 1.0 (2023) and opened 17 August 2026. Used for context-dependent human roles, responsibility, variation in human-AI interaction, and override evidence. NIST states that AI RMF 1.0 is being updated. The framework is voluntary and does not certify a workflow, security control, or release decision.
- Google PAIR, “People + AI Guidebook: All Worksheets”, opened 17 August 2026. Used for practical prompts on automation versus augmentation, user expectations for control, sensitive and high-stakes situations, error recovery, explanations, and validation through user research. The worksheets are design aids, not current empirical findings or a safety standard.
- The Confirmation-Budget Canvas, four treatment categories, checkpoint payload, fictional renewal scenario, outcome measures, accessibility implications, and drift triggers are original Fred editorial contributions. They are qualitative decision aids, not validated instruments, customer outcomes, legal advice, authorization controls, or claims that Fred executes or governs autonomous agents.
Keep exploring
Related Resources
Continue with editorially selected guides that add context to this topic.
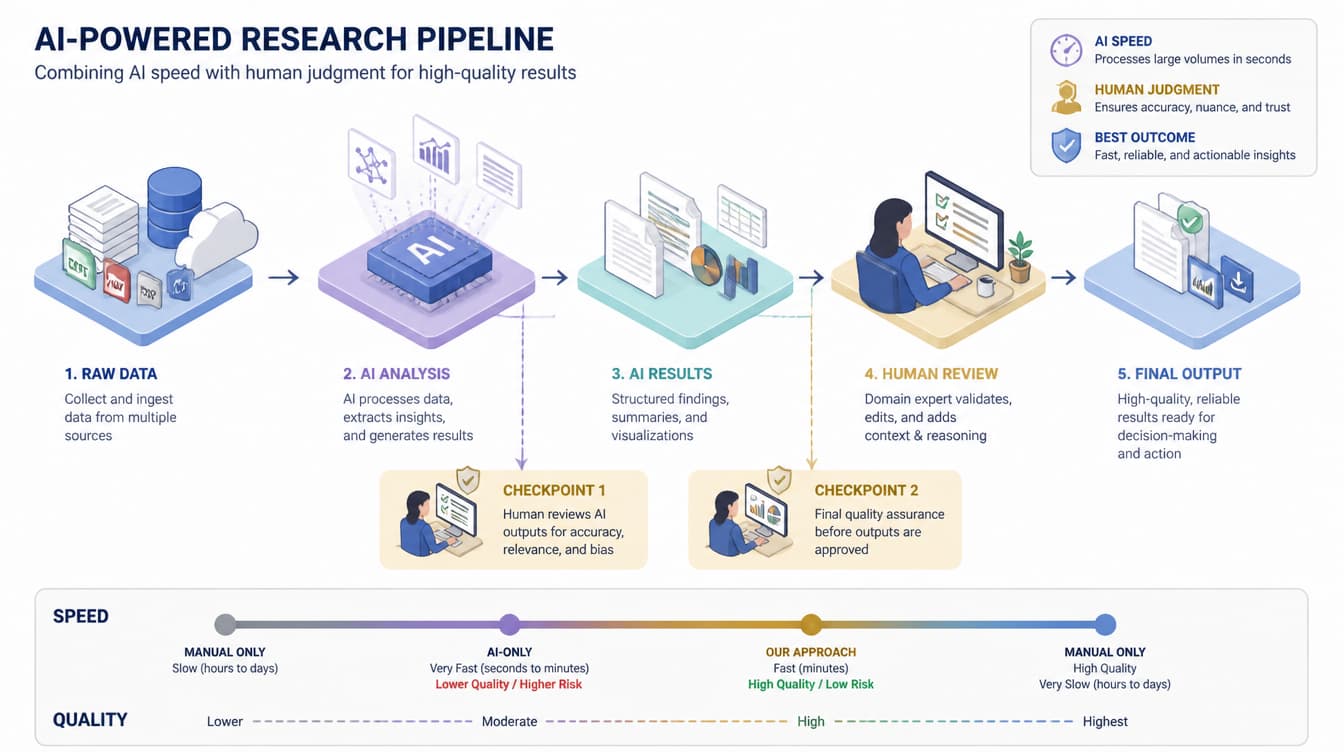
AI in UX Research: How to Use Automation Without Losing Insight Quality
AI in UX research can accelerate the process, but weak pipelines create meaning drift. Learn how to evaluate AI-assisted research, protect evidence quality, and turn findings into decisions.
Read guide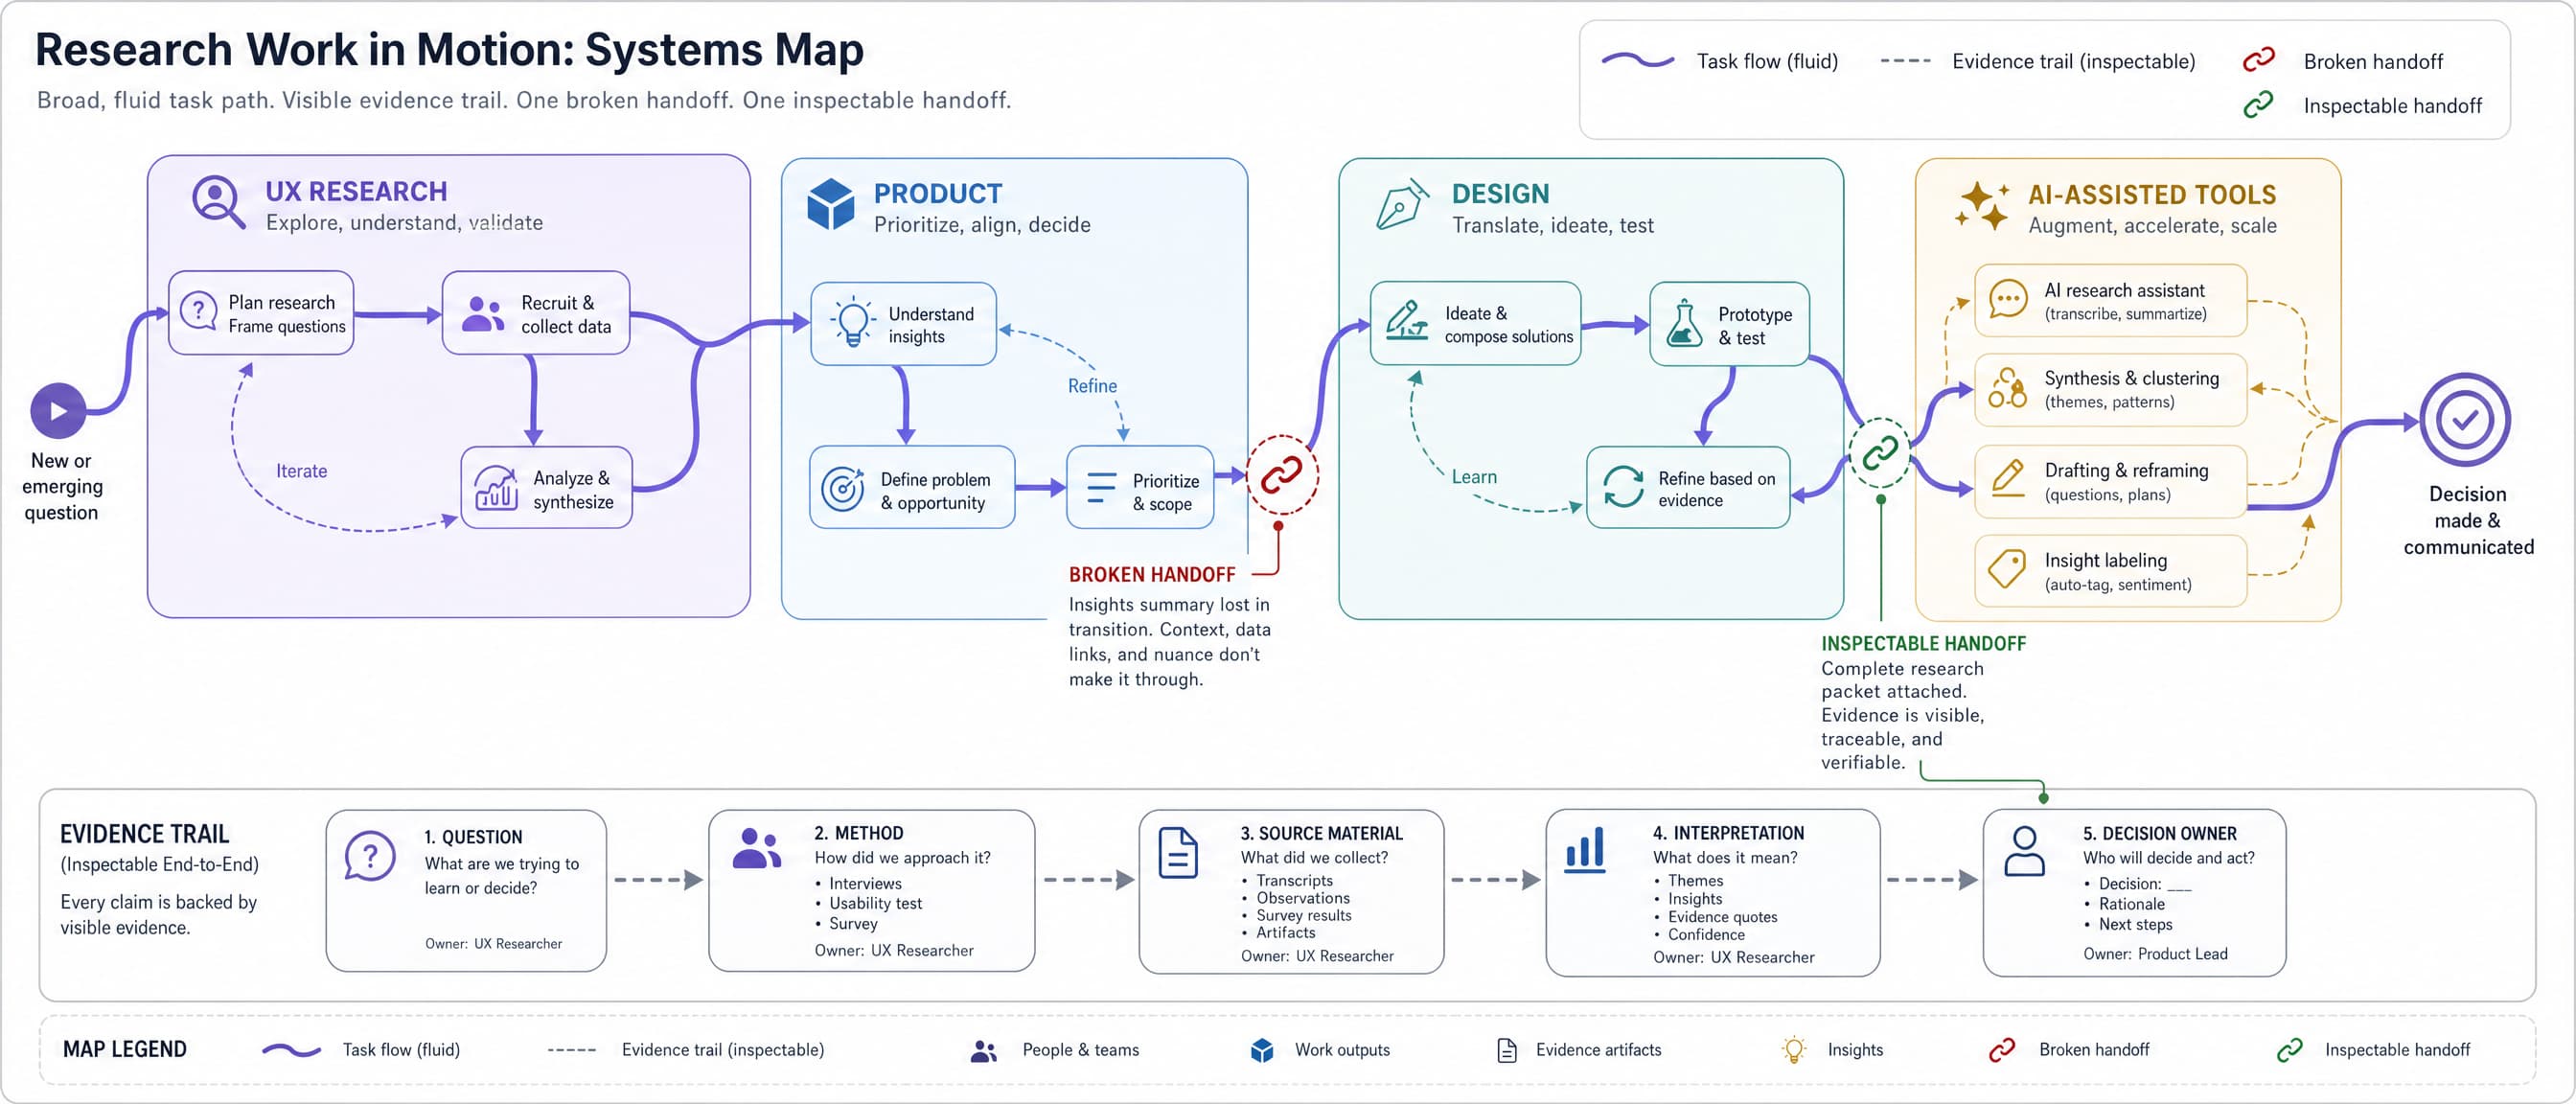
AI Is Expanding UX Work. Who Owns the Evidence?
How to govern AI-enabled UX task crossover with explicit method, evidence, interpretation, reuse, and decision ownership.
Read guide
AI-Powered UX Research in 2026: What It Actually Means and Which Tools Do It Right
What AI-powered UX research actually does, where it transforms the work, where it still fails, and how to evaluate AI research tools beyond the marketing claims.
Read guide